Tag: Pim

Product information management: the system that owns the product record, its typed attributes, and the completeness rules each channel imposes on it.

  • Do you need a PIM yet?

    Do you need a PIM yet?

    The answer most vendors will give you is yes, and the answer most consultants will give you is yes but later. Neither is wrong exactly. Both are unfalsifiable.

    Short answer: you need a PIM when at least two of four things are true. More than one market with genuinely different values, more than two channels with different required fields, more than one person editing the same records, and a variant structure a spreadsheet row cannot represent. One of the four is survivable. Two is the point where the spreadsheet starts costing more than the software.

    The four conditions, and why each one bites

    A second market with different values. Not a translated site. A market where units differ, where regulatory fields appear, where the category placement is not the same, and where copy has to be written rather than converted. A spreadsheet handles this by adding columns, and the column count becomes the problem: fields times markets, most of them empty, none of them validated.

    A third channel with its own required fields. Two channels can be handled with two tabs. At three, the tabs disagree, and the disagreement is discovered by a rejection report. The cost here is not the columns, it is that no single place tells you whether a product is ready.

    More than one editor. The moment two people edit the same file, you have a concurrency problem being solved by social convention. It works until a launch week, which is exactly when it will not.

    A variant structure that does not fit a row. One row per sellable unit means the product-level attributes are duplicated across every variant. One row per product means the variant data is crammed into a delimited string. Both are workable at small scale and neither survives a catalogue where variants outnumber products five to one. The modelling detail is in attributes, variants and the SKU problem.

    Notice what is not on the list. Revenue is not on it. Headcount is not on it. SKU count is only on it indirectly, because ten thousand simple products in one market on one channel are genuinely fine in a spreadsheet, and four hundred complex ones across five markets are not.

    What to do in the eighteen months before you need one

    This is the part that gets skipped, and it is the part that determines how bad the eventual migration is.

    Model properly now, in whatever you have. The four decisions in the product data model that survives growth can all be made in a spreadsheet. Typed columns, one column per attribute with a unit column beside it, a separate sheet for variants keyed to a parent, and an explicit note about what is localisable. A well-modelled spreadsheet migrates in an afternoon. A badly modelled one migrates over a quarter and mostly by hand.

    Use identifiers that will survive. A meaningless permanent internal SKU, never reused, plus a real GTIN where you sell through anyone else. This costs nothing today and is close to unfixable later.

    Keep the vocabularies as lists. A separate sheet per controlled field, and a validation rule pointing at it. You will not enforce everything a real system would, but the lists themselves are the asset, and they transfer.

    Write down the channel requirements. One page per channel, with its required fields and constraints, dated. This is the input to the rule sets you will eventually configure, and gathering it later, under time pressure, is miserable.
    Macro of a printed ruled grid on paper under raking teal light, one cell carrying an amber correction mark over the printed rule

    The media half of the question is different

    The threshold for a PIM is genuinely high. The threshold for putting media on a proper delivery layer is much lower, and the two questions get bundled together when they should not be.

    Product data in a spreadsheet has few second-order effects. Product images in a folder have several, and they start immediately: every channel needs a different shape, so someone produces crops; those crops become files; the files go stale independently; nothing records which one is current; and the front end serves whatever oversized JPEG it was given. That is happening at forty products, not at four thousand.

    This is where adopting something on day one genuinely pays, and it is a smaller commitment than the PIM decision. A delivery layer that derives renditions from a master by URL parameter removes the crop production step permanently, and it does so at a scale where nothing else about your operation needs to change. Cloudinary’s free Programmable Media tier covers 25 credits a month, where a credit is 1,000 transformations or 1 GB of storage or 1 GB of delivery, which is a real amount of capacity for a small catalogue rather than a trial.

    The argument for doing it early is not that you will grow. It is that the structure is there from the first upload, and the alternative is discovering at month eighteen that four hundred stored derivatives exist across three codebases with no record of which master they came from. The developer-facing version of this is in DAM for developers.

    What if you buy one too early?

    You get three things you did not need and one you did.

    The three: a workflow to maintain, a schema you configured before you understood your own catalogue, and a licence line. The one: enforcement, which genuinely does improve data quality even for a small catalogue.

    Buying early is not a disaster. It is a cost with a modest benefit, and the real risk is that you configure the schema wrong while you are still learning what your product data looks like, then live with that configuration for years because reconfiguring is a project. This is the strongest argument for modelling on paper first, which costs an afternoon and is reversible.
    A horizontal bar in three zones, three pale squares in the first, nine in the second, thirty tightly packed in the third with four in amber

    What if you wait too long?

    You get a migration with a data cleanup attached, and the cleanup is the expensive half. It is also the half that cannot be parallelised, because it consists of decisions about values only a few people can make.

    The signals that you are past the point are specific. Someone maintains a document explaining which spreadsheet is the real one. A launch slips because two versions of a file diverged. A channel rejection takes more than a day to attribute to a field. Any of those means the cost has already moved from the software to the operation, which is a worse place for it to sit.

    So what should you do this quarter?

    Three things, in this order, none of which requires a purchase.

    1. Test yourself against the four conditions honestly. If fewer than two are true, do not buy a PIM. Revisit in six months.
    2. Fix the model where you are. Types, variants, localisable fields, identifiers. This is the work that makes the eventual purchase cheap.
    3. Put the media on a delivery layer now, because that threshold is lower and the debt accrues faster.

    When two conditions do become true, what a DAM and a PIM actually cost sets out what to budget, build versus buy for the product catalogue covers the case for assembling it yourself, and alternatives to buying a DAM and a PIM covers what you can do with tools you already pay for. The system boundary you are buying into either way is in DAM vs PIM, and the honest description of what the category does is in what a PIM actually does.
  • DAM, PIM, CMS and ERP: the boundary map

    DAM, PIM, CMS and ERP: the boundary map

    The vendor comparison pages are all written from inside one of the four categories, which is why they all conclude that the category they are written from should be the centre of your architecture. Read four of them and you will have four incompatible architectures, each internally consistent.

    The map below is written from outside all four.

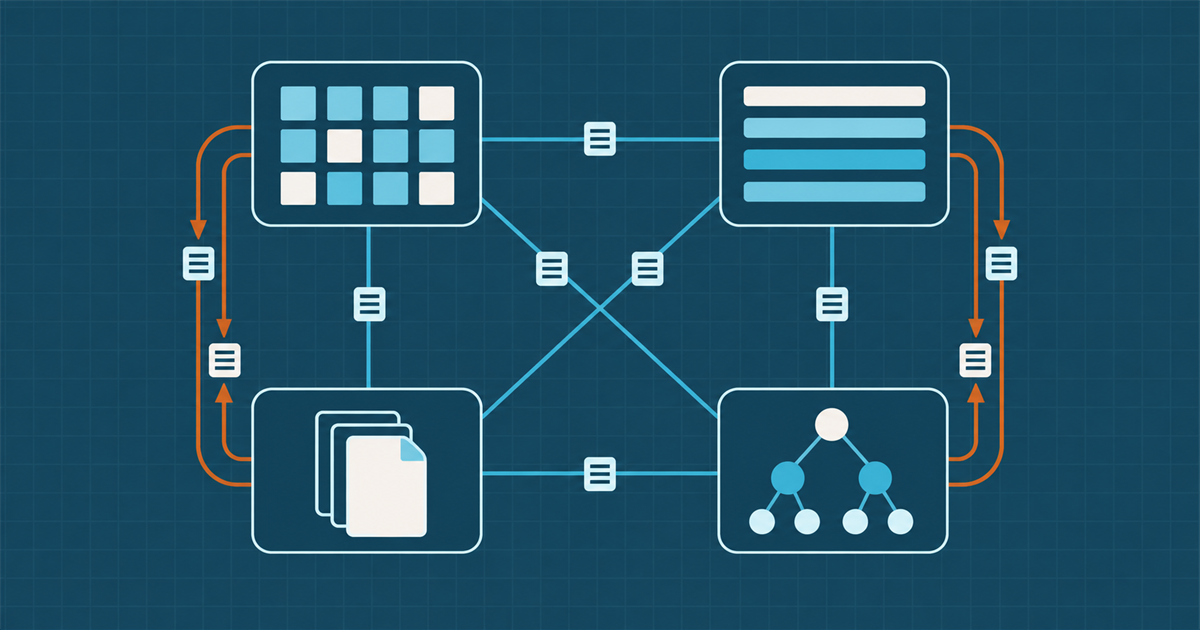
    Short answer: the DAM owns the asset, the PIM owns the product record, the CMS owns the page, and the ERP owns the transaction. For any disputed field, ask which of those four things the field describes. That resolves most of them outright, and the leftovers are worth arguing about properly because they are genuinely contested.

    What each one is for

    DAM. The visual and rich media object, and everything intrinsic to it. What the asset depicts, who made it, what rights attach, which version is current, how it renders for a destination. Digital asset management as a category covers more than this in practice, but the intrinsic-to-the-asset test is the useful one. The longer version is in what a DAM actually does.

    PIM. Structured product information. Identifiers, attributes, variant structure, category placement, per-market copy, and channel completeness rules. Product information management exists because product data has hundreds of attributes across dozens of markets and a supply chain of contributors, and nothing else handles that shape well. See what a PIM actually does.

    CMS. Page and component structure, and editorial content that is not about a product. Which components sit on which page, in what order, with what copy, published when. A content management system is a composition tool. Its record is the page, not the things the page references.

    ERP. The transactional record. Stock, cost, purchase orders, suppliers, fulfilment, financials. Enterprise resource planning is upstream of everything above and is usually the system nobody in a marketing conversation wants to talk about, right up until someone asks where the cost price comes from.

    The field map

    Field by field, here is where authority usually lands.

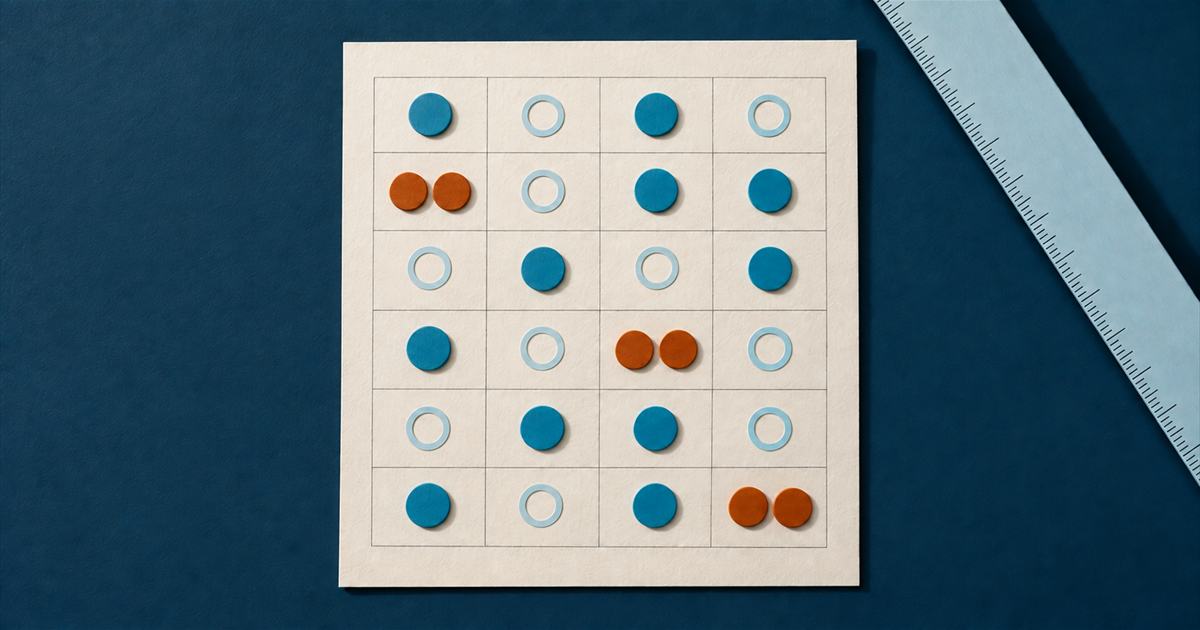
    The DAM owns: master files and renditions, what an asset depicts, creator and shoot data, licence terms and expiry, releases, approval state, colour profile, asset version history, default image description.

    The PIM owns: SKU and GTIN, attributes and specifications, units, variant structure, commerce category placement, per-market product copy, channel rules, and the product-to-asset association.

    The CMS owns: page and component structure, navigation, editorial copy that is not product copy, publication scheduling for pages, and the choice of which asset appears in which slot.

    The ERP owns: stock levels, cost price, supplier and purchase data, fulfilment state, and the canonical existence of a product as a thing the business transacts in.

    Two of those deserve emphasis because they get placed wrong most often. The product-to-asset association belongs in the PIM, not the DAM, because it is a fact about the product rather than about the photograph. The canonical product identity usually originates in the ERP, not the PIM, because a product exists as a purchasable thing before anyone writes marketing copy about it. Getting the second one backwards produces two competing definitions of what a product is, which is the problem master data management exists to solve and which you would rather not need.

    A responsibility matrix on card, teal discs for ownership and hollow rings for consumption, three cells holding two discs and marked amber

    The two genuinely contested boundaries

    Most of the map is uncontroversial once written down. Two areas are not, and pretending otherwise wastes a lot of workshop time.

    Alt text and image descriptions. The DAM’s claim is that the text describes the image and should be reusable everywhere the image appears. The CMS’s claim is that good alt text is contextual, and the same photograph legitimately needs different text on a category tile, a size guide and a press page. Both are correct.

    The workable answer is two fields rather than one argument. The DAM holds a default description of what is depicted, which is intrinsic. The placing surface may override it, which is contextual, and the override is the exception rather than the norm. MDN’s guidance on the img element and the WCAG overview both support that reading: alt text serves the function of the image in context, and the context is not always known at asset level.

    Product copy in the CMS. Marketing wants long-form product storytelling built as page components, with layout. The PIM wants product copy as structured fields so it can be syndicated. Both are legitimate needs and they are not the same content.

    The rule that holds: copy that has to go to a channel other than your own site belongs in the PIM as a field. Copy that only ever appears on your own site, as part of a designed page, belongs in the CMS as a component. If a piece of copy has to do both, it is a PIM field and the CMS composes around it.

    How many of these do you need?

    Fewer than four, for most people, and the answer changes with catalogue shape rather than with company size.

    • Under a few hundred products, simple attributes, one market. The CMS or the storefront platform can carry product data. Skip the PIM until attribute count or locale count makes it painful, which is usually somewhere around a thousand SKUs or three markets.
    • One brand, one market, no third-party rights. The CMS media library may genuinely be enough and adding a DAM adds an integration without adding an answer.
    • Any real inventory or fulfilment. You have an ERP whether you call it that or not, and its data will be authoritative for the transactional fields regardless of what your architecture diagram says.
    • Multi-market, multi-channel, seasonal reshoots. You need all four and you need the boundary written down before any of them is bought.

    What you should not do is buy a system to solve a problem another one owns. A DAM bought to fix product data will not fix product data. A PIM bought to manage images will manage them badly, in a schema designed for attributes. A CMS asked to be the product master becomes the thing you replatform away from. DAM vs PIM sets out the two-system version of the same decision.

    Four filing volumes in a ring joined by teal bridges, with a single unsupported amber block floating between two of the bridges

    What do you do when two systems both offer the same feature?

    Three questions, in order.

    1. Which system holds the record this field describes? Licence expiry describes an image. Net weight describes a product. Component order describes a page. Stock describes a transaction. Most fields stop here.
    2. Which system’s users maintain it? A field maintained by cataloguers, placed in a system cataloguers never open, will be empty forever. Where question one leaves room, authority should follow the workflow.
    3. Which system can enforce it? Controlled vocabulary and validation in one, free text in the other, is not a real choice. Enforcement wins.

    Write the answers into an ownership matrix and get it signed by the owner of each system. That single artefact prevents more integration rework than any other document in the programme, and it becomes the input to the integration design in wiring a DAM to a PIM and the operating discipline in single source of truth applied to product data.

  • What a PIM actually does

    What a PIM actually does

    The demo always shows the same thing: a clean grid of products, a completeness percentage climbing toward one hundred, and a button that pushes everything to six marketplaces. It is an accurate demo. It is also the last five per cent of the work, and it hides what the system is actually for.

    Short answer: a PIM holds one authoritative record per product, made of typed and validated attributes, and knows what each destination channel requires from that record. Its real job is refusing to publish incomplete data and telling you exactly which field is missing for which market. Everything else the category sells you is secondary to that.

    The problem it exists to solve

    You sell one product. A marketplace wants a title under eighty characters, five bullet points, a GTIN, a specific category code from its own taxonomy, and a square image on white. Your own storefront wants a longer title, a paragraph of prose, and a lifestyle image. A retail partner wants dimensions in millimetres and net weight in grams. A comparison engine wants a price, a stock state and a shipping class.

    That is one product and four incompatible shapes. The version of this problem everyone starts with is a spreadsheet per channel, which works until a specification changes and only three of the four spreadsheets get updated.

    Product information management is the category name for storing the union of those requirements once, in typed fields, and generating each channel’s shape on demand. The value is not the storage. It is that the union is stated somewhere a machine can check.

    What is actually inside the record

    Four layers, and they are worth separating because teams tend to collapse them and then cannot explain why the model will not scale.

    Identifiers. The SKU you control, plus the external identifiers you do not: GTIN, EAN, MPN. GS1 maintains the identifier standards and marketplaces increasingly reject listings without a valid one, so this layer is not optional even for small catalogues.

    Attributes. Typed values with units and controlled vocabularies. Not “colour: navy blue-ish” but a colour attribute drawn from a fixed list. The typing is the point: an attribute with a type can be validated, converted between units, and filtered on. An attribute stored as free text can only be searched.

    Structure. Which products are variants of which, which belong to which category, and how they group into families. Attributes, variants and the SKU problem covers this layer in detail, because it is where most models break.

    Channel context. Per-channel, per-market overrides and completeness rules. This is the layer that makes a PIM different from a database with a nice interface.

    A specification card with a ruled grid of empty label and value cells, a third filled solid teal, four cells carrying an amber corner fold

    Completeness is the feature

    If you take one idea from this page, take this one. A PIM’s core loop is:

    1. A channel declares its requirements as a rule set. Title length, required attributes, allowed category codes, image count and aspect ratio.
    2. Every product is continuously scored against every rule set it is meant to satisfy.
    3. Publishing is blocked, per channel, until the score is complete.

    That inverts the usual failure. Without it, incomplete data reaches the channel, gets rejected asynchronously, and someone finds out three days later from a report nobody reads. With it, the gap is visible before anything is sent, and it is attributable to a person and a field.

    Google’s product data specification is a good public example of what one such rule set looks like, and the Product schema is a reasonable minimum shape to model against if you are starting from nothing.

    Localisation, which is the part that gets underestimated

    A second market is not a translation job. It is a second set of values for a subset of your attributes, with different units, different regulatory fields, different category placement, and prose that has to be written rather than converted.

    The modelling decision is which attributes are localisable and which are global. Net weight is global. Marketing copy is localisable. Colour name is localisable even though the colour itself is global, which is the sort of distinction that looks pedantic in a workshop and saves a migration later.

    Get this wrong in the direction of “everything is localisable” and you have multiplied your empty fields by the number of markets. Get it wrong the other way and you will be doing a schema change in the middle of a launch.

    A fanned stack of eight identical thin plates, each with the same slot pattern, five filled teal, two partially pale, one with an empty amber slot

    What a PIM does not do

    The category has expanded to the point where vendors claim most of the adjacent surface, so it is worth being blunt about the edges.

    • It is not a DAM. It stores references to assets, not the assets themselves, and its search and rights handling are not built for a media library. The division is set out in DAM vs PIM.
    • It is not an ERP. Stock levels, cost prices, purchase orders and supplier terms belong upstream in the enterprise resource planning system. A PIM reads them at most.
    • It is not a CMS. It does not own page layout, navigation, or editorial content that is not about a product.
    • It is not a storefront. It publishes to one. Treating it as the customer-facing database usually produces a slow storefront and a PIM under read load it was never sized for.

    When is a spreadsheet still the right answer?

    More often than the vendors suggest, and the honest thresholds are these.

    A spreadsheet holds up while all of the following are true: one market, one or two channels, under a few hundred products, attributes that rarely change shape, and one person who owns the file. Under those conditions a PIM adds process without removing work.

    It stops holding up at the first of these: a second market with its own units and copy, a third channel with its own required fields, more than one person editing at once, or a variant structure deep enough that a row can no longer represent a product. That last one is the most common trigger and the least anticipated.

    Do you need a PIM yet works through the arithmetic, including the case for staying on the spreadsheet for another year. Whatever you choose, model the data properly before you choose the tool, because the product data model outlives every platform it has ever been stored in.

  • DAM vs PIM: which system owns which record

    DAM vs PIM: which system owns which record

    Someone in the room says the product images should live in the PIM, because images belong to products. Someone else says they should live in the DAM, because that is what a DAM is for. Both people are describing the same photograph and both are partly right, which is why the meeting runs long and ends with a decision to “sync them”.

    That decision is the expensive one.

    Short answer: a DAM owns the asset and everything intrinsic to it. A PIM owns the product record and everything intrinsic to that. The image file, its rights, its version history and what it depicts belong to the DAM. The statement “these six images depict SKU 44-2210” belongs to the PIM, because it is a fact about the product, not about the photograph. Get that one line right and most boundary arguments answer themselves.

    What each system is actually holding

    Strip out the feature overlap that every vendor adds to compete with the other category, and two very different shapes remain.

    A digital asset management system holds files that are expensive to produce and reused in many places. Its record is the asset. It cares about the master file, the renditions derived from it, who shot it, what licence attaches, when that licence expires, which version is current, and what the image shows. Its hard problems are storage, search, rights and delivery. There is more on the shape of that record in what a DAM actually does.

    A product information management system holds structured facts about things you sell. Its record is the product. It cares about identifiers, attributes, variants, category placement, per-market copy and completeness against a channel’s requirements. Its hard problems are schema, validation, localisation and syndication. What a PIM actually does covers that side.

    The overlap is small and it is always the same three things: the association between products and images, alt text, and crops.

    The authority rule

    Write this into the architecture decision record before anyone opens a vendor site:

    For every field, exactly one system is authoritative. Every other system that displays that field holds a reference, not a copy. If a second system must store the value for performance, it stores it as a cache with a defined refresh, and it is never edited there.

    The failure this prevents is the only one that really hurts: two systems that both allow editing of the same field. That produces divergence, and divergence in a field like licence expiry or net weight is not untidiness. It is a defect with a legal or commercial consequence.

    The corollary matters as much as the rule. “We will sync it both ways” is nearly always the wrong answer, because bidirectional sync between two editable systems is a conflict resolution problem, and conflict resolution gets designed at the end of the project by whoever is left.

    Two matte volumes, a wide tray of image plates and a tall cabinet of drawers, joined by a single teal beam, with one amber drawer appearing in both

    The field-by-field map

    This is not universal, but every exception should be deliberate and written down.

    The DAM owns: the master file and its renditions, what the asset depicts, creator and shoot date, licence terms and expiry, model and property releases, approval state, colour profile, asset version history, and a default description of the image.

    The PIM owns: product identifiers including SKU and GTIN, attributes and specifications, variant structure, category placement in the commerce sense, per-market marketing copy, pricing structure, channel completeness rules, and the association between a product and its assets.

    Nobody owns anything twice. The association is the case people get backwards most often. It belongs in the PIM. The DAM holds the photograph; the PIM holds the sentence “this photograph shows this SKU”. Put that association in the DAM and you have quietly built a second product catalogue inside your asset library, with none of the validation and none of the channel rules.

    The same reasoning extends to the CMS and the ERP, which have their own claims on some of these fields. The boundary map works through all four.

    The three genuine arguments

    Most of the map is uncontroversial once it is written down. Three areas are not.

    Alt text. The DAM has the better claim, because the text describes the image and the image is reusable. The CMS and PIM have a real counter-argument, because good alt text is contextual and the same photograph legitimately needs different text on a category tile and in a size guide. The workable answer is two fields rather than one fight: the DAM holds a default description of what is depicted, and the surface that places the image may override it. MDN’s guidance on the img element supports that reading, since alt text serves the function of the image in its context and the context is not known at asset level.

    Crops and renditions. Historically both systems stored their own files, produced by someone, kept somewhere, going stale independently. The clean answer removes the argument rather than settling it: neither system stores a crop, and both request one by parameter at the point of use. When a rendition is derived rather than stored, there is no artefact to own. Platforms built around URL-level transformation, Cloudinary being the most complete example, turn this governance dispute into a query string.

    Enrichment copy. Marketing copy about a product goes in the PIM. Copy about an asset, such as a caption or a credit line, goes in the DAM. The grey area is the campaign description that mentions both, and the honest answer is that it usually belongs in whichever system the people writing it already work in.

    A responsibility grid of six rows and four columns marked with teal discs and hollow rings, with three cells holding two marks and rendered in amber

    Do you need both?

    Often not, and this is the question the comparison pages never ask.

    • Under a few hundred SKUs, one market, one channel: your storefront platform’s own product fields and media library are genuinely enough. Adding either system adds an integration without adding an answer. Do you need a PIM yet sets out the thresholds.
    • Many SKUs, few images: you need a PIM and probably not a DAM. Industrial and component catalogues live here. The images are line drawings and spec sheets, and the storefront can hold them.
    • Few SKUs, many images: you need a DAM and probably not a PIM. Fashion, furniture and anything shot repeatedly per season sits here. Twelve hundred photographs of forty products is an asset problem wearing a product costume.
    • Both, at volume, across markets: you need both, and you need the boundary written down before either is bought.

    What you should not do is buy one system to fix a problem the other one owns. A DAM bought to clean up product data will not clean up product data, and a PIM bought to manage images will manage them badly, in a schema designed for attributes. The cost comparison shows what that mistake looks like on an invoice.

    How do you decide when both systems offer the same feature?

    Three questions, in order. They resolve almost everything.

    1. Which system holds the record this field describes? Licence expiry describes an image, and the image is in the DAM. Net weight describes a product, and the product is in the PIM. Most fields stop here.
    2. Which system’s users maintain it? If photographers and cataloguers maintain a field and they work in the DAM, putting the field in the PIM guarantees it stays empty. Authority should follow the workflow wherever the first question leaves room.
    3. Which system can enforce it? A field with a controlled vocabulary and validation in one system and free text in the other is not really a choice. Enforcement wins, because an unenforced field becomes an inconsistent field, and an inconsistent field becomes a field nobody trusts.

    Write the answers into an ownership matrix, get it signed by whoever owns each system, and keep it where the integration team can find it. That single artefact prevents more rework than any other document in the project, and it is the input to single source of truth applied to product data, which is where the rule gets tested against real fields.

    Related field note

    Continue with A migration plan for catalog rollback plans.