Tag: Syndication

Generating each channel’s shape from one record, and validating against that channel’s rules before anything is sent.

  • Syndicating product data to marketplaces

    Syndicating product data to marketplaces

    The feed goes out on Monday. On Thursday a report says four hundred listings were rejected. The reasons are terse, the affected SKUs are listed by the marketplace’s own identifier rather than yours, and nobody can tell whether it is the same four hundred as last week.

    That loop is the entire problem, and it is a loop you can close.

    Short answer: treat every channel’s requirements as a declared rule set, hold the union of all of them in one record, and validate against each rule set before publishing rather than after. Rejection then happens in your system, attributable to a field and a person, instead of arriving three days later in someone else’s format.

    What a channel actually demands

    Pull apart any marketplace specification and it contains four kinds of requirement, which is useful because each needs a different mechanism.

    Required fields. Present and non-empty. Easy to check, and the most common cause of rejection.

    Format constraints. Title under a length, description without HTML, price with two decimals, image at a minimum resolution and aspect ratio. Also easy to check, and routinely missed because the constraint is buried in a PDF.

    Vocabulary mapping. The channel’s category tree, its colour list, its size conventions. Your Navy has to become their Blue, and there is no way to derive that. It has to be maintained as a mapping.

    Identity. A valid GTIN with a computing check digit, or an approved exemption. This is increasingly non-negotiable and it is the failure that takes longest to fix, because obtaining identifiers is an external process.

    Google’s product data specification is the best public example to read if you want to see all four in one document, and its shape is broadly representative of what the larger marketplaces want.

    Hold the union, generate the shapes

    The instinct is to build a record per channel. It works for two channels and collapses at four.

    The alternative is one record holding the union of every field any channel needs, plus a mapping layer per channel that selects, renames, converts and constrains. The record does not know about channels. The mapping does not hold data. Adding a fifth channel is then a new mapping and possibly a few new fields, rather than a fifth copy of everything.

    Two properties make this work in practice:

    Mappings are declarative. A mapping should be a document that says which source field becomes which target field, with which transformation. When mappings are code, only the person who wrote them can answer a question about them, and channel specifications change often enough that this matters.

    Generation is idempotent. Running the same export twice produces the same output, and publishing it twice produces the same state at the channel. Without that property you cannot safely retry, and you will need to retry.
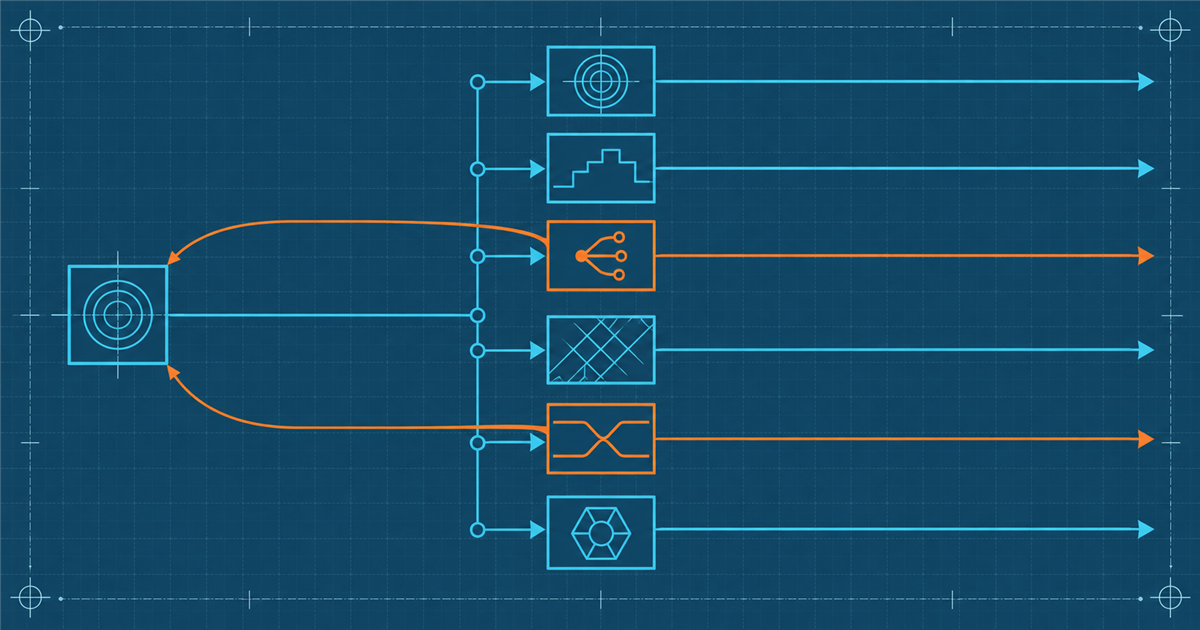
    A schematic of one source block feeding six transform blocks each emitting one output, two of the blocks amber with a rejection arrow curving back

    Validate before you publish

    This is the change that removes most of the pain, and it is the reason the completeness model in what a PIM actually does exists.

    Score every product against every rule set it is meant to satisfy, continuously. Show the result as a per-channel completeness figure with the missing fields named. Block publication for a product that does not pass. The queue of work then lives in your system, sorted by channel and field, and it can be assigned.

    Compare that with the alternative, which is that the channel validates for you, in its own time, and reports in its own vocabulary. The information is the same. The latency and the attribution are not, and those are what determine whether anything gets fixed.

    One caution worth stating: a completeness score is only as honest as the rule set behind it. Rule sets drift when a channel updates its specification quietly, which they do. Put a date on each rule set and review it, or your green dashboard will eventually be measuring last year’s requirements.

    Images are part of the feed and they fail differently

    Channels have image requirements: minimum dimensions, aspect ratio, background colour, no text overlay, a maximum file size, sometimes a specific format. These are the requirements most likely to be met by generating rather than by finding.

    If your renditions are derived from a master by parameter, meeting a new channel’s image spec is a mapping entry rather than a production task. A square crop on white at 2000 pixels for one marketplace and a 4:5 crop for another are two parameter strings against the same master, not two files someone makes and stores. The rendition model is what makes that possible, and it is the difference between adding a channel in an afternoon and adding one in a sprint.

    The image identity question is separate and worth being careful about. Some channels key on image URL and will re-fetch when it changes; others cache the first version they saw. Use stable URLs for the same content, change the URL when the content genuinely changes, and never reuse a URL for a different image.
    A tray of small embossed metal labels under raking teal light, five in the third row stamped off-centre and lit amber

    Rejection handling as a first-class flow

    You will still get rejections, because channels enforce things they did not document. Treat that as a routine flow rather than an incident.

    • Map their identifier back to yours on ingest, so a rejection report arrives as your SKUs. This single step saves more time than any other.
    • Classify by cause, not by product. Four hundred rejections are usually six causes. Fix the cause and the four hundred resolve together.
    • Feed the cause back into the rule set. Every undocumented rule you discover becomes a check you run before publishing, permanently. This is how the rule sets become more accurate than the specifications.
    • Keep the history. The same product failing repeatedly for different reasons means the record is thin, not that the channel is difficult.

    How often should a feed run?

    Less often than you think for the full catalogue, and much more often than you think for changes.

    A full regeneration is a reconciliation, not an update. Run it on a schedule that suits the channel’s tolerance, typically daily or weekly, and treat divergence found by it as a bug in the change path rather than as normal operation.

    Changes should propagate on change. Price and stock in particular have a short useful life, and a channel showing yesterday’s stock costs you more than the engineering to push it. Where a channel only accepts scheduled files, generate the file from live data at generation time rather than from a staged copy you maintain, which is the same argument made about internal integrations in wiring a DAM to a PIM.

    The structural prerequisite for all of this is a model that can express what the channels ask for. If yours cannot represent a variant grid or a localised attribute, the mapping layer will end up carrying data, which is where syndication projects go to die. Attributes, variants and the SKU problem and the product data model that survives growth cover that groundwork, and the human side of keeping the queue moving is in running product content as an operation.
  • What a PIM actually does

    What a PIM actually does

    The demo always shows the same thing: a clean grid of products, a completeness percentage climbing toward one hundred, and a button that pushes everything to six marketplaces. It is an accurate demo. It is also the last five per cent of the work, and it hides what the system is actually for.

    Short answer: a PIM holds one authoritative record per product, made of typed and validated attributes, and knows what each destination channel requires from that record. Its real job is refusing to publish incomplete data and telling you exactly which field is missing for which market. Everything else the category sells you is secondary to that.

    The problem it exists to solve

    You sell one product. A marketplace wants a title under eighty characters, five bullet points, a GTIN, a specific category code from its own taxonomy, and a square image on white. Your own storefront wants a longer title, a paragraph of prose, and a lifestyle image. A retail partner wants dimensions in millimetres and net weight in grams. A comparison engine wants a price, a stock state and a shipping class.

    That is one product and four incompatible shapes. The version of this problem everyone starts with is a spreadsheet per channel, which works until a specification changes and only three of the four spreadsheets get updated.

    Product information management is the category name for storing the union of those requirements once, in typed fields, and generating each channel’s shape on demand. The value is not the storage. It is that the union is stated somewhere a machine can check.

    What is actually inside the record

    Four layers, and they are worth separating because teams tend to collapse them and then cannot explain why the model will not scale.

    Identifiers. The SKU you control, plus the external identifiers you do not: GTIN, EAN, MPN. GS1 maintains the identifier standards and marketplaces increasingly reject listings without a valid one, so this layer is not optional even for small catalogues.

    Attributes. Typed values with units and controlled vocabularies. Not “colour: navy blue-ish” but a colour attribute drawn from a fixed list. The typing is the point: an attribute with a type can be validated, converted between units, and filtered on. An attribute stored as free text can only be searched.

    Structure. Which products are variants of which, which belong to which category, and how they group into families. Attributes, variants and the SKU problem covers this layer in detail, because it is where most models break.

    Channel context. Per-channel, per-market overrides and completeness rules. This is the layer that makes a PIM different from a database with a nice interface.

    A specification card with a ruled grid of empty label and value cells, a third filled solid teal, four cells carrying an amber corner fold

    Completeness is the feature

    If you take one idea from this page, take this one. A PIM’s core loop is:

    1. A channel declares its requirements as a rule set. Title length, required attributes, allowed category codes, image count and aspect ratio.
    2. Every product is continuously scored against every rule set it is meant to satisfy.
    3. Publishing is blocked, per channel, until the score is complete.

    That inverts the usual failure. Without it, incomplete data reaches the channel, gets rejected asynchronously, and someone finds out three days later from a report nobody reads. With it, the gap is visible before anything is sent, and it is attributable to a person and a field.

    Google’s product data specification is a good public example of what one such rule set looks like, and the Product schema is a reasonable minimum shape to model against if you are starting from nothing.

    Localisation, which is the part that gets underestimated

    A second market is not a translation job. It is a second set of values for a subset of your attributes, with different units, different regulatory fields, different category placement, and prose that has to be written rather than converted.

    The modelling decision is which attributes are localisable and which are global. Net weight is global. Marketing copy is localisable. Colour name is localisable even though the colour itself is global, which is the sort of distinction that looks pedantic in a workshop and saves a migration later.

    Get this wrong in the direction of “everything is localisable” and you have multiplied your empty fields by the number of markets. Get it wrong the other way and you will be doing a schema change in the middle of a launch.

    A fanned stack of eight identical thin plates, each with the same slot pattern, five filled teal, two partially pale, one with an empty amber slot

    What a PIM does not do

    The category has expanded to the point where vendors claim most of the adjacent surface, so it is worth being blunt about the edges.

    • It is not a DAM. It stores references to assets, not the assets themselves, and its search and rights handling are not built for a media library. The division is set out in DAM vs PIM.
    • It is not an ERP. Stock levels, cost prices, purchase orders and supplier terms belong upstream in the enterprise resource planning system. A PIM reads them at most.
    • It is not a CMS. It does not own page layout, navigation, or editorial content that is not about a product.
    • It is not a storefront. It publishes to one. Treating it as the customer-facing database usually produces a slow storefront and a PIM under read load it was never sized for.

    When is a spreadsheet still the right answer?

    More often than the vendors suggest, and the honest thresholds are these.

    A spreadsheet holds up while all of the following are true: one market, one or two channels, under a few hundred products, attributes that rarely change shape, and one person who owns the file. Under those conditions a PIM adds process without removing work.

    It stops holding up at the first of these: a second market with its own units and copy, a third channel with its own required fields, more than one person editing at once, or a variant structure deep enough that a row can no longer represent a product. That last one is the most common trigger and the least anticipated.

    Do you need a PIM yet works through the arithmetic, including the case for staying on the spreadsheet for another year. Whatever you choose, model the data properly before you choose the tool, because the product data model outlives every platform it has ever been stored in.