Insights

  • Attributes, variants and the SKU problem

    Attributes, variants and the SKU problem

    A merchandiser asks how many products you have. The answer is either four hundred or eleven thousand, depending on who is counting, and both people are confident. That is not a reporting problem. It is the model showing through.

    Short answer: a SKU is a unit you sell. A product is a thing you describe. A variant is a product that differs from its siblings in a small, enumerated set of axes. Model these as three distinct levels, put each attribute at the highest level where it is still true, and the maintenance problem largely disappears.

    The three levels

    Family. Defines which attributes exist. All shirts have a fabric composition, a collar type and a fit. A family is a schema, not a thing you sell, and most catalogues need surprisingly few of them.

    Product. Carries the values shared by everything beneath it. The fabric composition of the Oxford shirt. Its care instructions, its brand, its story. This is the level a customer thinks they are browsing.

    Variant. Carries only what differs, along a small number of declared axes. Colour and size, usually. Sometimes a third, and if you find yourself needing a fourth it is worth checking whether one of them is really a separate product.

    The SKU is the identifier of the sellable unit, which is normally the variant. It is an inventory concept that has been borrowed by everyone else, which is why the same word means different things in a warehouse conversation and a merchandising one.

    Put each attribute at the highest level where it is still true

    That single rule does most of the work.

    Fabric composition is true of every variant of the shirt, so it sits on the product. Colour is not, so it sits on the variant. Weight is interesting: usually true at product level, occasionally variant level if sizes differ enough to matter for shipping, and if you are not sure, the safe answer is variant with a default inherited from the product.

    The failure mode when you get this wrong in the “too low” direction is duplication: the fabric composition stored thirty times, edited in twenty-nine places, wrong in one. The failure mode in the “too high” direction is a lie: a single weight value that is wrong for the extra large.

    Duplication is the more expensive of the two, because it degrades silently. A wrong value announces itself eventually. Thirty copies of a value that were all correct at the time just drift.

    The combinatorics, which nobody models for

    Six colours times five sizes is thirty variants. Add a fit and it is ninety. Add a market with its own copy and it is ninety times the number of markets in the fields that are localisable.

    That number is fine when it is generated and enforced. It is unmanageable when it is entered.

    Two consequences follow. First, variant creation should be generated from the declared axes, not typed, so that the thirty exist because six times five is thirty and not because someone made thirty rows. Second, the axes have to be enumerated in the model, so that “which colours does this come in” is a query rather than an inspection.

    There is also the case of the incomplete grid, which is normal and worth modelling deliberately. Not every colour comes in every size. A generated grid with explicit exclusions is maintainable. A hand-built list of the twenty-three combinations that exist is not, because nobody will remember why the other seven are missing.
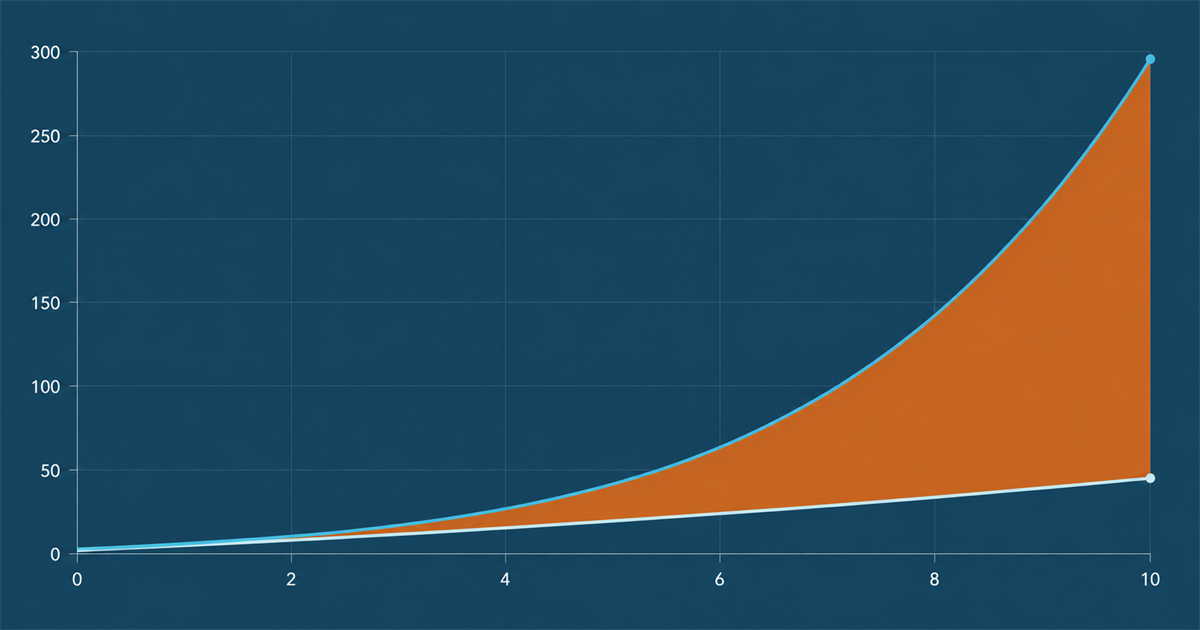
    A steep teal curve against a flat pale baseline with the widening gap between them shaded amber

    Identifiers, and why you need more than one

    The catalogue needs at least three kinds of identifier and they are not interchangeable.

    Your internal identifier. Stable, meaningless, and never reused. Meaningless matters: an identifier that encodes the category will be wrong the first time a product is recategorised, and you will not be allowed to change it because it is printed on something.

    The external trade identifier. GTIN, EAN or UPC, issued under the GS1 system. Marketplaces increasingly reject listings without a valid one, and validity means the check digit computes and the prefix is actually yours. Borrowed or invented barcodes fail at the worst moment.

    The manufacturer’s identifier. MPN, if you resell. It is the only reliable way to reconcile your record with a supplier’s, and it is the field that makes data synchronisation with trading partners possible at all.

    Keep them in separate fields. The pattern of jamming several identifiers into one string with a separator survives until the first supplier whose identifier contains that separator.

    Where do images fit in the variant structure?

    At every level, and this is the part that catches people.

    Some images are true of the family, such as a size chart. Some are true of the product, such as a detail shot of the fabric. Most are true of the variant, because the blue one and the red one look different. A few are true of a combination that is not a variant axis, such as a lifestyle shot showing three colours together.

    The model that works is an association with a role, held on the product side: this asset, in this role, for this product or variant. Roles are a controlled list. Primary, alternate, detail, lifestyle, size chart, packaging. The channel mapping then says “the marketplace wants the primary plus up to six alternates”, and that is a query rather than a folder convention.

    What the model should not do is put the association in the asset system, for the reasons in DAM vs PIM, and it should not store crops per variant, because renditions are derived rather than stored.
    Macro of a fanned colour swatch deck under raking teal light with two identical amber blades sitting side by side

    When is flattening variants actually correct?

    Twice, and it is worth naming them because the general advice above is otherwise absolute.

    When variants are genuinely different products. If the blue one and the red one have different specifications, different regulatory status, different suppliers and different marketing, they are two products that happen to look similar. Forcing them into a variant grid produces a parent record with almost nothing on it.

    When your only channel demands it. Some marketplaces model everything as a flat list of sellable items with no parent concept. That is a channel mapping problem, not a modelling problem, and the correct response is to keep the structured model and flatten at export. The exception is if you have exactly one channel, forever, and no site of your own, in which case matching its model is defensible and you should write down that you did it on purpose.

    Everything else that looks like a reason to flatten is usually a tool that cannot express hierarchy, which is a reason to check the tool. The questions to ask about that are in what to demand from a PIM API before you buy, and the export-side consequences are in syndicating product data to marketplaces.

    The wider set of modelling decisions this one sits inside is in the product data model that survives growth, and if you are still working out whether a dedicated system is warranted at all, start with what a PIM actually does.
  • DAM, PIM, CMS and ERP: the boundary map

    DAM, PIM, CMS and ERP: the boundary map

    The vendor comparison pages are all written from inside one of the four categories, which is why they all conclude that the category they are written from should be the centre of your architecture. Read four of them and you will have four incompatible architectures, each internally consistent.

    The map below is written from outside all four.

    Short answer: the DAM owns the asset, the PIM owns the product record, the CMS owns the page, and the ERP owns the transaction. For any disputed field, ask which of those four things the field describes. That resolves most of them outright, and the leftovers are worth arguing about properly because they are genuinely contested.

    What each one is for

    DAM. The visual and rich media object, and everything intrinsic to it. What the asset depicts, who made it, what rights attach, which version is current, how it renders for a destination. Digital asset management as a category covers more than this in practice, but the intrinsic-to-the-asset test is the useful one. The longer version is in what a DAM actually does.

    PIM. Structured product information. Identifiers, attributes, variant structure, category placement, per-market copy, and channel completeness rules. Product information management exists because product data has hundreds of attributes across dozens of markets and a supply chain of contributors, and nothing else handles that shape well. See what a PIM actually does.
    CMS. Page and component structure, and editorial content that is not about a product. Which components sit on which page, in what order, with what copy, published when. A content management system is a composition tool. Its record is the page, not the things the page references.

    ERP. The transactional record. Stock, cost, purchase orders, suppliers, fulfilment, financials. Enterprise resource planning is upstream of everything above and is usually the system nobody in a marketing conversation wants to talk about, right up until someone asks where the cost price comes from.

    The field map

    Field by field, here is where authority usually lands.

    The DAM owns: master files and renditions, what an asset depicts, creator and shoot data, licence terms and expiry, releases, approval state, colour profile, asset version history, default image description.

    The PIM owns: SKU and GTIN, attributes and specifications, units, variant structure, commerce category placement, per-market product copy, channel rules, and the product-to-asset association.

    The CMS owns: page and component structure, navigation, editorial copy that is not product copy, publication scheduling for pages, and the choice of which asset appears in which slot.

    The ERP owns: stock levels, cost price, supplier and purchase data, fulfilment state, and the canonical existence of a product as a thing the business transacts in.

    Two of those deserve emphasis because they get placed wrong most often. The product-to-asset association belongs in the PIM, not the DAM, because it is a fact about the product rather than about the photograph. The canonical product identity usually originates in the ERP, not the PIM, because a product exists as a purchasable thing before anyone writes marketing copy about it. Getting the second one backwards produces two competing definitions of what a product is, which is the problem master data management exists to solve and which you would rather not need.

    A responsibility matrix on card, teal discs for ownership and hollow rings for consumption, three cells holding two discs and marked amber

    The two genuinely contested boundaries

    Most of the map is uncontroversial once written down. Two areas are not, and pretending otherwise wastes a lot of workshop time.

    Alt text and image descriptions. The DAM’s claim is that the text describes the image and should be reusable everywhere the image appears. The CMS’s claim is that good alt text is contextual, and the same photograph legitimately needs different text on a category tile, a size guide and a press page. Both are correct.

    The workable answer is two fields rather than one argument. The DAM holds a default description of what is depicted, which is intrinsic. The placing surface may override it, which is contextual, and the override is the exception rather than the norm. MDN’s guidance on the img element and the WCAG overview both support that reading: alt text serves the function of the image in context, and the context is not always known at asset level.

    Product copy in the CMS. Marketing wants long-form product storytelling built as page components, with layout. The PIM wants product copy as structured fields so it can be syndicated. Both are legitimate needs and they are not the same content.

    The rule that holds: copy that has to go to a channel other than your own site belongs in the PIM as a field. Copy that only ever appears on your own site, as part of a designed page, belongs in the CMS as a component. If a piece of copy has to do both, it is a PIM field and the CMS composes around it.

    How many of these do you need?

    Fewer than four, for most people, and the answer changes with catalogue shape rather than with company size.

    • Under a few hundred products, simple attributes, one market. The CMS or the storefront platform can carry product data. Skip the PIM until attribute count or locale count makes it painful, which is usually somewhere around a thousand SKUs or three markets.
    • One brand, one market, no third-party rights. The CMS media library may genuinely be enough and adding a DAM adds an integration without adding an answer.
    • Any real inventory or fulfilment. You have an ERP whether you call it that or not, and its data will be authoritative for the transactional fields regardless of what your architecture diagram says.
    • Multi-market, multi-channel, seasonal reshoots. You need all four and you need the boundary written down before any of them is bought.

    What you should not do is buy a system to solve a problem another one owns. A DAM bought to fix product data will not fix product data. A PIM bought to manage images will manage them badly, in a schema designed for attributes. A CMS asked to be the product master becomes the thing you replatform away from. DAM vs PIM sets out the two-system version of the same decision.

    Four filing volumes in a ring joined by teal bridges, with a single unsupported amber block floating between two of the bridges

    What do you do when two systems both offer the same feature?

    Three questions, in order.

    1. Which system holds the record this field describes? Licence expiry describes an image. Net weight describes a product. Component order describes a page. Stock describes a transaction. Most fields stop here.
    2. Which system’s users maintain it? A field maintained by cataloguers, placed in a system cataloguers never open, will be empty forever. Where question one leaves room, authority should follow the workflow.
    3. Which system can enforce it? Controlled vocabulary and validation in one, free text in the other, is not a real choice. Enforcement wins.

    Write the answers into an ownership matrix and get it signed by the owner of each system. That single artefact prevents more integration rework than any other document in the programme, and it becomes the input to the integration design in wiring a DAM to a PIM and the operating discipline in single source of truth applied to product data.

  • The product image workflow, shoot to storefront

    The product image workflow, shoot to storefront

    Ask a merchandising team why a product launched without images and you will get a story about the photographer. Ask the photographer and you will hear that the images were delivered three weeks ago. Both are telling the truth, and the gap between them is where the work actually stalls.

    Short answer: map the pipeline as a sequence of handoffs and measure the wait between each pair, not the duration of each step. In almost every catalogue operation the bottleneck is a single queue, usually retouching approval or metadata entry, and it is invisible because everyone is measuring their own step and reporting it as fast.

    The seven handoffs

    Written out, a typical pipeline for one product looks like this. Yours will differ in the details and not in the shape.

    1. Sample arrives. Someone books it in, and it either gets a shoot slot or waits for one.
    2. Shoot. Frames are captured against a known setup, ideally the same setup as last season.
    3. Ingest. Raw files land somewhere, are backed up, and get a first identifier.
    4. Selection. Someone picks the frames that will be used. This is fast and is nearly always waiting on someone senior.
    5. Retouch. Cleanup, colour, background. This is slow and is often outsourced, which adds a round trip.
    6. Approval. Brand or merchandising signs off. This is the queue.
    7. Catalogue. Metadata entered, asset associated with a product record, published.

    Between each pair there is a wait. The sum of the waits usually exceeds the sum of the work by a factor of three or more, which is why hiring another retoucher rarely helps.

    Measure the waits, not the steps

    Instrument this crudely before you buy anything. For fifty recent products, record one timestamp per handoff. You do not need a system for this; a shared sheet for two weeks is enough to find the answer.

    Two numbers matter. Touch time is the total of the work itself. Lead time is the wall clock from sample arrival to published. The ratio between them tells you where you are. A well-run operation is somewhere around one to four. Most are one to fifteen, and everyone in the chain is genuinely busy.

    Then look at the single largest gap. It is nearly always one of three: samples waiting for a shoot slot, retouched files waiting for approval, or finished files waiting for someone to type metadata. Each has a different fix, and buying a platform is only the fix for the third one.

    A five-stage pipeline schematic with duration brackets under three stages and a wide amber hatched wedge between stages three and four

    Capture metadata at the point it is known

    The metadata queue is self-inflicted and it is the easiest of the three to remove.

    Most of what ends up being typed later was known at shoot time. Which product this is. Which angle. Which season and campaign. Who shot it. The set it belongs to. Typing it a week later, from a filename, by someone who was not there, is both slower and less accurate.

    The mechanics are unglamorous and they work:

    • Shoot into a named structure. A directory per SKU, or a capture template that writes the SKU into the file’s metadata at capture. IPTC photo metadata fields are written by most capture and editing software and survive most exports, and ExifTool will tell you whether yours survived.
    • Use the shot list as the data source. The list already contains the SKU, the angle and the required frames. It is a manifest. Ingesting against it means the association is made by matching, not by typing.
    • Let automatic extraction do the mechanical fields. Dimensions, format, capture date and camera settings should never be entered by a person. Subject tagging can be proposed automatically as well, which is useful for search recall and should not be trusted for approval state or rights.
    • Enter judgement fields once, deliberately. Approval, rights, and the default description are the fields worth a human. Everything else should arrive by itself.

    Stop producing crops as a pipeline step

    Steps five and seven in most pipelines include producing the six or eight sizes each channel needs. That work is real, it is repeated per asset, and it produces files that go stale independently of the master.

    It is also avoidable. If renditions are derived from the master on request, the pipeline ends at the approved master and the channels take what they need. That removes a step, removes a storage problem, and removes the class of bug where a product page updates and the marketplace listing does not.

    This is the operational reason to prefer a delivery layer that transforms by URL rather than a folder of exports. The transformation model turns eight export tasks into eight parameter strings, and the mechanics of that are in what a DAM actually does.

    Three trays on a dark tabletop, the left full under teal light, the middle half full, the right holding one object under an amber lamp

    The approval queue

    This is the hardest one, because it is a people problem wearing a process costume.

    Three things reliably shorten it:

    Approve sets, not files. A reviewer looking at four hundred individual images will batch them mentally anyway, badly. Present the shoot as a set with a contact sheet and let approval happen at set level, with exceptions flagged individually.

    Define what approval means. Half of all approval delay is a reviewer who is not sure whether they are checking brand compliance, retouching quality, or product accuracy. Write down which, and route each to the person who can answer it. Three fast reviews in parallel beat one slow one that covers everything.

    Give it a deadline that has a default. Unreviewed after five working days means approved, or means escalated, but it has to mean something. A queue with no timeout is not a queue, it is a place things go.

    What should you fix first?

    In this order, because the earlier ones make the later ones cheaper.

    1. The metadata queue, by capturing at the point of knowledge. Cheapest fix, fastest payback, no purchase required.
    2. The crop step, by deriving renditions instead of producing them. One integration change, and it removes work permanently.
    3. The approval queue, by changing what approval means and who does it. Free, slow, and political.
    4. The shoot slot, which is usually a capacity question and the only one that costs money. Product photography without a studio backlog covers the ways to add throughput without adding a studio.

    Do not start by buying a workflow tool. A tool imposed on an unmeasured pipeline formalises the queue rather than removing it. Once the shape is known, the wider operating model, including who owns which step and what happens at seasonal peak, is in running product content as an operation. The launch-day version of the same checklist is in the catalogue launch checklist.

    Related field note

    Continue with The hidden cost of product taxonomy ownership.

  • Wiring a DAM to a PIM without a nightly sync job

    Wiring a DAM to a PIM without a nightly sync job

    The integration gets specified in one line on a whiteboard: “the PIM pulls images from the DAM overnight”. Six months later there is a queue, a staging directory, a retry script, a spreadsheet of failed transfers, and a rule that nobody publishes on Thursdays.

    The line on the whiteboard was the problem. Everything after it was consequence.

    Short answer: do not copy assets or asset metadata into the product system. Store a stable asset identifier on the product record and resolve it to a delivery URL at request time. The integration becomes a reference plus a URL contract, there is nothing to schedule, nothing to reconcile, and nothing that can be stale, because nothing was copied.

    Why the scheduled copy fails, specifically

    It is worth naming the failure modes rather than asserting that batch is bad, because plenty of batch integrations are fine and this particular one is not.

    It is stale by construction. Between two runs, the product system holds a claim about an asset that may no longer be true. If the window is twenty-four hours, your worst case is a day of serving a withdrawn image. That is a compliance question, not a latency question.

    Failures are silent and asynchronous. A run that half completes leaves the two systems in a state neither of them can describe. The person who finds out is a customer.

    It duplicates governance. Once the licence expiry date exists in both systems, one of them is wrong, and you now need a rule about which. That rule is the beginning of a reconciliation layer, and reconciliation layers grow.

    It cannot answer new questions. Six months on, a channel wants a 4:5 crop. The batch has been copying 1:1 and 16:9. Now you are changing the pipeline, backfilling, and re-running against the full catalogue.

    The general shape here is extract, transform, load, which is the correct tool for moving analytical data and the wrong one for keeping two operational systems in agreement about the same object.

    The reference contract

    Three pieces, and they are all small.

    One: the product record stores an identifier, not a file. A stable string that means “this asset” for the life of the asset. Not a URL, because URLs carry delivery parameters and those change. Not a filename, because filenames get edited. An identifier.

    Two: the asset system resolves an identifier plus a set of parameters into a delivery URL. This is the whole API surface you need for reads, and it is why the pattern works: the URL can be constructed by the consumer rather than requested from the provider. In Cloudinary the identifier is the public ID and the parameters sit in the URL path, so a storefront can build the exact URL it needs without a round trip to the asset system at all.

    Three: changes are pushed, not polled. When an asset is replaced, withdrawn or re-approved, the asset system emits an event and interested systems react. Webhook notifications are the standard mechanism. What you cache, you cache with an explicit invalidation path rather than a fixed interval.

    That is the entire integration. No staging directory, no queue you maintain, no Thursday rule.

    Two matte volumes joined by a single taut teal filament through a ring, with a slack amber cable discarded on the ground beneath

    What about the metadata the product system genuinely needs?

    This is the fair objection, and it has a fair answer.

    Some asset metadata really does need to be queryable from the product side. Merchandising wants to filter products whose primary image is missing. Legal wants a list of products using assets that expire this quarter. Neither of those can be answered if the asset metadata lives entirely elsewhere and is only resolvable one record at a time.

    The answer is a read model, not a copy. Maintain a projection of the few asset fields the product side needs to query, populated by events, explicitly labelled as derived, and never editable in the product system. Three fields is typical: asset exists, approval state, expiry date. That is a cache with a defined invalidation, which is exactly what the authority rule in DAM vs PIM permits.

    The discipline is that nobody may add a fourth field to the projection without saying which query needs it. Left ungoverned, a read model becomes a full copy in about a year, and you are back where you started.

    The crop problem, which is where most of the copying comes from

    Look at any batch integration between an asset library and a product catalogue and most of the volume is not masters. It is derivatives: the square one for the marketplace, the wide one for the hero, the small one for the cart.

    Those exist as files because at some point a system needed a shape and the only way to get it was to make one. If renditions are derived from the master by parameter, that entire class of transfer disappears. The product system stores one identifier, and each surface asks for the shape it needs at the point of use. Named transformations are worth using here rather than raw parameter strings, because they give each shape a name your storefront code can refer to, and let you change the definition later without editing the consumers.

    There is a governance caveat worth stating plainly, because vendor material tends to skate over it. Access control in most asset platforms, Cloudinary included, is organised at the folder level rather than per asset, and there is no general API for traversing arbitrary relationships between assets. Design the integration so it does not depend on either. Model the product-to-asset relationship on the product side, where it belongs anyway, and use folder structure to carry the permission boundaries you actually need.

    A timeline of twelve teal scheduled ticks with irregular pale change bars above, three ticks replaced by amber crosses leaving changes unpaired

    When is a scheduled export still correct?

    Three cases, and they are real.

    • The destination cannot make an outbound call. Some marketplace and retailer feeds accept a file on a schedule and nothing else. That is their contract and you meet it. Generate the feed from live data at generation time rather than from a copy you keep, and the rest of this page still applies upstream of it.
    • You are migrating. A one-time bulk move is a batch job by nature. Cloudinary’s migration tooling exists for exactly this, and it should terminate rather than become a schedule.
    • Analytical reporting. Copying into a warehouse for analysis is fine, because nothing operational reads from it.

    Everything else that is currently a schedule is a reference waiting to be written.

    How do you migrate an existing sync to references?

    Incrementally, and in this order. Add the identifier field to the product record and populate it from the existing copies, which you can usually do by matching on filename or hash. Switch one surface, ideally a low-traffic one, to resolve from the identifier. Add the event subscription so the read model stays current. Then stop the batch and delete the staging directory, which is the step teams postpone for a year because the old pipeline is still technically working.

    The API-side questions to ask the product platform before you commit to any of this are in what to demand from a PIM API before you buy, and the wider principle is in single source of truth applied to product data. If the four-system version of the boundary is still unclear, DAM, PIM, CMS and ERP maps it. For the developer-facing case for adopting a derived-rendition model from the first upload rather than after the pipeline exists, see DAM for developers.

    Related field note

    Continue with Asset-to-SKU mapping without duplicate files.

  • The product data model that survives growth

    The product data model that survives growth

    Ask anyone who has replatformed a catalogue what went wrong and you will not hear about the platform. You will hear that the colour attribute was free text, that variants were modelled as separate products, that dimensions were stored as a string with the unit in it, and that by the end nobody could write a query that returned a reliable answer.

    None of those are platform problems. They are modelling decisions, made early, cheaply, by someone under time pressure.

    Short answer: four decisions determine whether a product model survives. Whether attributes are typed, how variants relate to their parent, which fields are localisable, and whether the model is enforced or merely documented. Everything else can be changed later. These four get baked into every downstream integration within about six months.

    Decision one: type every attribute, including the ones that look like text

    An attribute has a type, a unit where relevant, and a vocabulary where the values are drawn from a set. Free text is a type of last resort, not a default.

    The test is whether you will ever want to filter, convert, validate or compare on the field. If yes, it is not text. If you want a public reference point for what a minimally typed product record looks like, the Product schema and its Offer companion are a reasonable floor rather than a ceiling.

    • Number with a unit. Store weight: 2.4 and weight_unit: kg as separate typed values, never "2.4 kg". The moment a market wants pounds you will thank yourself, and the moment a marketplace requires grams you will not have to write a parser.
    • Enumeration. Colour, material, closure type, certification. Draw from a list. The list can be extended; free text cannot be un-extended.
    • Boolean. dishwasher_safe: true, not a text field containing “yes”, “Yes”, “y” and “safe for dishwasher”.
    • Date. Launch date, discontinuation date, certification expiry. Dates as strings sort alphabetically, which is a bug waiting for a locale change.
    • Reference. A link to another record, whether that is a category, a related product or an asset identifier. Never a copy of the other record’s fields.

    The cost of typing late is not the schema change. It is the cleanup pass over existing values, which is manual, and which nobody will fund.

    Decision two: variants are children, not siblings

    This is the modelling error that causes the most rework, and it is invisible for the first year.

    A t-shirt in six colours and five sizes is one product with thirty variants. It is not thirty products, and it is not one product with a text field containing a size list. The distinction matters because the shared attributes have to live in exactly one place.

    The workable structure has three levels: a family that defines which attributes exist, a product that carries the values shared across all its variants, and a variant that carries only the values that differ. Fabric composition sits on the product. Size and colour sit on the variant. Price may sit on either, depending on your business, and if you cannot say which, that is worth resolving before you build anything.

    Model variants as separate products and every shared attribute gets copied thirty times, which means it gets updated in twenty-nine places and missed in one. Attributes, variants and the SKU problem goes through the combinatorics and the two cases where flattening genuinely is correct.

    Three relationship motifs in a row, one-to-one and one-to-many drawn cleanly in teal, many-to-many drawn in amber as a tangled knot

    Decision three: decide what is localisable, and be stingy

    Every attribute is either global or per-market. Choosing badly in either direction hurts.

    Mark everything localisable and you multiply your empty cells by the number of markets, and your completeness reporting becomes noise. Mark nothing localisable and you will be doing a schema migration during a market launch, which is the worst possible time.

    The rule that holds up: an attribute is localisable if its value legitimately differs by market, not if its presentation does. Net weight is global; the fact that one market displays it in pounds is a presentation concern and belongs in the channel mapping, not in the data. Colour is global; the colour name is localisable, because “taupe” is not a word in every market. Marketing copy is localisable by definition. Regulatory fields are localisable and are usually forgotten until the first compliance review.

    A useful discipline is to keep a fourth category: attributes that are global today but have a plausible market-specific future. Do not localise them, but do note them, so that the eventual change is a decision rather than a discovery.

    Decision four: enforce it, or accept that it is fiction

    A schema that is documented but not enforced describes what people intended, not what is in the database. After a year those two things have very little in common.

    Enforcement means the system rejects a value that is not in the vocabulary, refuses to save a required field as empty, and blocks publication to a channel whose rules are not met. It has to happen at write time. Validation reports that run nightly are a way of measuring how bad it got, not of preventing it.

    This is also the honest argument for a dedicated system over a spreadsheet, and it is a narrower argument than the category marketing makes. A spreadsheet can hold a good model. It cannot enforce one. If your model is enforced by convention and a shared understanding among three people, it will survive exactly as long as those three people do.

    Macro of index card edges in a drawer, punched notches aligned into a continuous groove, six cards in the middle notched wrong and lit amber

    Taxonomy, which is a separate thing from attributes

    Categories answer “where does this sit in a browsable hierarchy”. Attributes answer “what is true about this”. Teams routinely encode attributes into the category tree and end up with branches like Furniture > Chairs > Blue Chairs > Blue Oak Chairs, which cannot be maintained and cannot be filtered.

    Keep the taxonomy) shallow and about kind, not about properties. Four levels is usually plenty. Everything that feels like it needs a fifth level is an attribute wearing a category costume, and it should be filterable rather than navigable.

    Expect to maintain more than one taxonomy, because your browse structure and a marketplace’s required category codes will never be the same tree. The mapping problem is old enough to have its own standards work, and the GS1 global data synchronisation network exists largely because two trading partners never agree on one tree. Map between them explicitly rather than trying to satisfy both with one hierarchy.

    What should you model before choosing a platform?

    All four decisions above, on paper, against a real sample of your catalogue. Pick the twenty products that are most awkward, not the twenty that are easiest, and write out their full records by hand. The awkward ones are where the model breaks, and finding that in a document costs an afternoon rather than a quarter.

    Then check the platform against your model rather than the other way round. A tool that cannot express your variant structure will make you flatten it, and the flattening will be permanent. The API-level questions to ask are in what to demand from a PIM API before you buy.

    The model also has to agree with whatever holds your images, because the association between the two is itself a modelled relationship. That boundary is set out in DAM vs PIM, and the discipline that keeps it stable is in single source of truth applied to product data. If you are still deciding whether you need a dedicated system at all, what a PIM actually does is the honest version of the pitch.

  • What a PIM actually does

    What a PIM actually does

    The demo always shows the same thing: a clean grid of products, a completeness percentage climbing toward one hundred, and a button that pushes everything to six marketplaces. It is an accurate demo. It is also the last five per cent of the work, and it hides what the system is actually for.

    Short answer: a PIM holds one authoritative record per product, made of typed and validated attributes, and knows what each destination channel requires from that record. Its real job is refusing to publish incomplete data and telling you exactly which field is missing for which market. Everything else the category sells you is secondary to that.

    The problem it exists to solve

    You sell one product. A marketplace wants a title under eighty characters, five bullet points, a GTIN, a specific category code from its own taxonomy, and a square image on white. Your own storefront wants a longer title, a paragraph of prose, and a lifestyle image. A retail partner wants dimensions in millimetres and net weight in grams. A comparison engine wants a price, a stock state and a shipping class.

    That is one product and four incompatible shapes. The version of this problem everyone starts with is a spreadsheet per channel, which works until a specification changes and only three of the four spreadsheets get updated.

    Product information management is the category name for storing the union of those requirements once, in typed fields, and generating each channel’s shape on demand. The value is not the storage. It is that the union is stated somewhere a machine can check.

    What is actually inside the record

    Four layers, and they are worth separating because teams tend to collapse them and then cannot explain why the model will not scale.

    Identifiers. The SKU you control, plus the external identifiers you do not: GTIN, EAN, MPN. GS1 maintains the identifier standards and marketplaces increasingly reject listings without a valid one, so this layer is not optional even for small catalogues.

    Attributes. Typed values with units and controlled vocabularies. Not “colour: navy blue-ish” but a colour attribute drawn from a fixed list. The typing is the point: an attribute with a type can be validated, converted between units, and filtered on. An attribute stored as free text can only be searched.

    Structure. Which products are variants of which, which belong to which category, and how they group into families. Attributes, variants and the SKU problem covers this layer in detail, because it is where most models break.

    Channel context. Per-channel, per-market overrides and completeness rules. This is the layer that makes a PIM different from a database with a nice interface.

    A specification card with a ruled grid of empty label and value cells, a third filled solid teal, four cells carrying an amber corner fold

    Completeness is the feature

    If you take one idea from this page, take this one. A PIM’s core loop is:

    1. A channel declares its requirements as a rule set. Title length, required attributes, allowed category codes, image count and aspect ratio.
    2. Every product is continuously scored against every rule set it is meant to satisfy.
    3. Publishing is blocked, per channel, until the score is complete.

    That inverts the usual failure. Without it, incomplete data reaches the channel, gets rejected asynchronously, and someone finds out three days later from a report nobody reads. With it, the gap is visible before anything is sent, and it is attributable to a person and a field.

    Google’s product data specification is a good public example of what one such rule set looks like, and the Product schema is a reasonable minimum shape to model against if you are starting from nothing.

    Localisation, which is the part that gets underestimated

    A second market is not a translation job. It is a second set of values for a subset of your attributes, with different units, different regulatory fields, different category placement, and prose that has to be written rather than converted.

    The modelling decision is which attributes are localisable and which are global. Net weight is global. Marketing copy is localisable. Colour name is localisable even though the colour itself is global, which is the sort of distinction that looks pedantic in a workshop and saves a migration later.

    Get this wrong in the direction of “everything is localisable” and you have multiplied your empty fields by the number of markets. Get it wrong the other way and you will be doing a schema change in the middle of a launch.

    A fanned stack of eight identical thin plates, each with the same slot pattern, five filled teal, two partially pale, one with an empty amber slot

    What a PIM does not do

    The category has expanded to the point where vendors claim most of the adjacent surface, so it is worth being blunt about the edges.

    • It is not a DAM. It stores references to assets, not the assets themselves, and its search and rights handling are not built for a media library. The division is set out in DAM vs PIM.
    • It is not an ERP. Stock levels, cost prices, purchase orders and supplier terms belong upstream in the enterprise resource planning system. A PIM reads them at most.
    • It is not a CMS. It does not own page layout, navigation, or editorial content that is not about a product.
    • It is not a storefront. It publishes to one. Treating it as the customer-facing database usually produces a slow storefront and a PIM under read load it was never sized for.

    When is a spreadsheet still the right answer?

    More often than the vendors suggest, and the honest thresholds are these.

    A spreadsheet holds up while all of the following are true: one market, one or two channels, under a few hundred products, attributes that rarely change shape, and one person who owns the file. Under those conditions a PIM adds process without removing work.

    It stops holding up at the first of these: a second market with its own units and copy, a third channel with its own required fields, more than one person editing at once, or a variant structure deep enough that a row can no longer represent a product. That last one is the most common trigger and the least anticipated.

    Do you need a PIM yet works through the arithmetic, including the case for staying on the spreadsheet for another year. Whatever you choose, model the data properly before you choose the tool, because the product data model outlives every platform it has ever been stored in.

  • DAM vs PIM: which system owns which record

    DAM vs PIM: which system owns which record

    Someone in the room says the product images should live in the PIM, because images belong to products. Someone else says they should live in the DAM, because that is what a DAM is for. Both people are describing the same photograph and both are partly right, which is why the meeting runs long and ends with a decision to “sync them”.

    That decision is the expensive one.

    Short answer: a DAM owns the asset and everything intrinsic to it. A PIM owns the product record and everything intrinsic to that. The image file, its rights, its version history and what it depicts belong to the DAM. The statement “these six images depict SKU 44-2210” belongs to the PIM, because it is a fact about the product, not about the photograph. Get that one line right and most boundary arguments answer themselves.

    What each system is actually holding

    Strip out the feature overlap that every vendor adds to compete with the other category, and two very different shapes remain.

    A digital asset management system holds files that are expensive to produce and reused in many places. Its record is the asset. It cares about the master file, the renditions derived from it, who shot it, what licence attaches, when that licence expires, which version is current, and what the image shows. Its hard problems are storage, search, rights and delivery. There is more on the shape of that record in what a DAM actually does.

    A product information management system holds structured facts about things you sell. Its record is the product. It cares about identifiers, attributes, variants, category placement, per-market copy and completeness against a channel’s requirements. Its hard problems are schema, validation, localisation and syndication. What a PIM actually does covers that side.

    The overlap is small and it is always the same three things: the association between products and images, alt text, and crops.

    The authority rule

    Write this into the architecture decision record before anyone opens a vendor site:

    For every field, exactly one system is authoritative. Every other system that displays that field holds a reference, not a copy. If a second system must store the value for performance, it stores it as a cache with a defined refresh, and it is never edited there.

    The failure this prevents is the only one that really hurts: two systems that both allow editing of the same field. That produces divergence, and divergence in a field like licence expiry or net weight is not untidiness. It is a defect with a legal or commercial consequence.

    The corollary matters as much as the rule. “We will sync it both ways” is nearly always the wrong answer, because bidirectional sync between two editable systems is a conflict resolution problem, and conflict resolution gets designed at the end of the project by whoever is left.

    Two matte volumes, a wide tray of image plates and a tall cabinet of drawers, joined by a single teal beam, with one amber drawer appearing in both

    The field-by-field map

    This is not universal, but every exception should be deliberate and written down.

    The DAM owns: the master file and its renditions, what the asset depicts, creator and shoot date, licence terms and expiry, model and property releases, approval state, colour profile, asset version history, and a default description of the image.

    The PIM owns: product identifiers including SKU and GTIN, attributes and specifications, variant structure, category placement in the commerce sense, per-market marketing copy, pricing structure, channel completeness rules, and the association between a product and its assets.

    Nobody owns anything twice. The association is the case people get backwards most often. It belongs in the PIM. The DAM holds the photograph; the PIM holds the sentence “this photograph shows this SKU”. Put that association in the DAM and you have quietly built a second product catalogue inside your asset library, with none of the validation and none of the channel rules.

    The same reasoning extends to the CMS and the ERP, which have their own claims on some of these fields. The boundary map works through all four.

    The three genuine arguments

    Most of the map is uncontroversial once it is written down. Three areas are not.

    Alt text. The DAM has the better claim, because the text describes the image and the image is reusable. The CMS and PIM have a real counter-argument, because good alt text is contextual and the same photograph legitimately needs different text on a category tile and in a size guide. The workable answer is two fields rather than one fight: the DAM holds a default description of what is depicted, and the surface that places the image may override it. MDN’s guidance on the img element supports that reading, since alt text serves the function of the image in its context and the context is not known at asset level.

    Crops and renditions. Historically both systems stored their own files, produced by someone, kept somewhere, going stale independently. The clean answer removes the argument rather than settling it: neither system stores a crop, and both request one by parameter at the point of use. When a rendition is derived rather than stored, there is no artefact to own. Platforms built around URL-level transformation, Cloudinary being the most complete example, turn this governance dispute into a query string.

    Enrichment copy. Marketing copy about a product goes in the PIM. Copy about an asset, such as a caption or a credit line, goes in the DAM. The grey area is the campaign description that mentions both, and the honest answer is that it usually belongs in whichever system the people writing it already work in.

    A responsibility grid of six rows and four columns marked with teal discs and hollow rings, with three cells holding two marks and rendered in amber

    Do you need both?

    Often not, and this is the question the comparison pages never ask.

    • Under a few hundred SKUs, one market, one channel: your storefront platform’s own product fields and media library are genuinely enough. Adding either system adds an integration without adding an answer. Do you need a PIM yet sets out the thresholds.
    • Many SKUs, few images: you need a PIM and probably not a DAM. Industrial and component catalogues live here. The images are line drawings and spec sheets, and the storefront can hold them.
    • Few SKUs, many images: you need a DAM and probably not a PIM. Fashion, furniture and anything shot repeatedly per season sits here. Twelve hundred photographs of forty products is an asset problem wearing a product costume.
    • Both, at volume, across markets: you need both, and you need the boundary written down before either is bought.

    What you should not do is buy one system to fix a problem the other one owns. A DAM bought to clean up product data will not clean up product data, and a PIM bought to manage images will manage them badly, in a schema designed for attributes. The cost comparison shows what that mistake looks like on an invoice.

    How do you decide when both systems offer the same feature?

    Three questions, in order. They resolve almost everything.

    1. Which system holds the record this field describes? Licence expiry describes an image, and the image is in the DAM. Net weight describes a product, and the product is in the PIM. Most fields stop here.
    2. Which system’s users maintain it? If photographers and cataloguers maintain a field and they work in the DAM, putting the field in the PIM guarantees it stays empty. Authority should follow the workflow wherever the first question leaves room.
    3. Which system can enforce it? A field with a controlled vocabulary and validation in one system and free text in the other is not really a choice. Enforcement wins, because an unenforced field becomes an inconsistent field, and an inconsistent field becomes a field nobody trusts.

    Write the answers into an ownership matrix, get it signed by whoever owns each system, and keep it where the integration team can find it. That single artefact prevents more rework than any other document in the project, and it is the input to single source of truth applied to product data, which is where the rule gets tested against real fields.

    Related field note

    Continue with A migration plan for catalog rollback plans.