Tag: Attributes

Typed values with units and controlled vocabularies. The difference between a field you can filter on and a field you can only search.

  • Attributes, variants and the SKU problem

    Attributes, variants and the SKU problem

    A merchandiser asks how many products you have. The answer is either four hundred or eleven thousand, depending on who is counting, and both people are confident. That is not a reporting problem. It is the model showing through.

    Short answer: a SKU is a unit you sell. A product is a thing you describe. A variant is a product that differs from its siblings in a small, enumerated set of axes. Model these as three distinct levels, put each attribute at the highest level where it is still true, and the maintenance problem largely disappears.

    The three levels

    Family. Defines which attributes exist. All shirts have a fabric composition, a collar type and a fit. A family is a schema, not a thing you sell, and most catalogues need surprisingly few of them.

    Product. Carries the values shared by everything beneath it. The fabric composition of the Oxford shirt. Its care instructions, its brand, its story. This is the level a customer thinks they are browsing.

    Variant. Carries only what differs, along a small number of declared axes. Colour and size, usually. Sometimes a third, and if you find yourself needing a fourth it is worth checking whether one of them is really a separate product.

    The SKU is the identifier of the sellable unit, which is normally the variant. It is an inventory concept that has been borrowed by everyone else, which is why the same word means different things in a warehouse conversation and a merchandising one.

    Put each attribute at the highest level where it is still true

    That single rule does most of the work.

    Fabric composition is true of every variant of the shirt, so it sits on the product. Colour is not, so it sits on the variant. Weight is interesting: usually true at product level, occasionally variant level if sizes differ enough to matter for shipping, and if you are not sure, the safe answer is variant with a default inherited from the product.

    The failure mode when you get this wrong in the “too low” direction is duplication: the fabric composition stored thirty times, edited in twenty-nine places, wrong in one. The failure mode in the “too high” direction is a lie: a single weight value that is wrong for the extra large.

    Duplication is the more expensive of the two, because it degrades silently. A wrong value announces itself eventually. Thirty copies of a value that were all correct at the time just drift.

    The combinatorics, which nobody models for

    Six colours times five sizes is thirty variants. Add a fit and it is ninety. Add a market with its own copy and it is ninety times the number of markets in the fields that are localisable.

    That number is fine when it is generated and enforced. It is unmanageable when it is entered.

    Two consequences follow. First, variant creation should be generated from the declared axes, not typed, so that the thirty exist because six times five is thirty and not because someone made thirty rows. Second, the axes have to be enumerated in the model, so that “which colours does this come in” is a query rather than an inspection.

    There is also the case of the incomplete grid, which is normal and worth modelling deliberately. Not every colour comes in every size. A generated grid with explicit exclusions is maintainable. A hand-built list of the twenty-three combinations that exist is not, because nobody will remember why the other seven are missing.
    A steep teal curve against a flat pale baseline with the widening gap between them shaded amber

    Identifiers, and why you need more than one

    The catalogue needs at least three kinds of identifier and they are not interchangeable.

    Your internal identifier. Stable, meaningless, and never reused. Meaningless matters: an identifier that encodes the category will be wrong the first time a product is recategorised, and you will not be allowed to change it because it is printed on something.

    The external trade identifier. GTIN, EAN or UPC, issued under the GS1 system. Marketplaces increasingly reject listings without a valid one, and validity means the check digit computes and the prefix is actually yours. Borrowed or invented barcodes fail at the worst moment.

    The manufacturer’s identifier. MPN, if you resell. It is the only reliable way to reconcile your record with a supplier’s, and it is the field that makes data synchronisation with trading partners possible at all.

    Keep them in separate fields. The pattern of jamming several identifiers into one string with a separator survives until the first supplier whose identifier contains that separator.

    Where do images fit in the variant structure?

    At every level, and this is the part that catches people.

    Some images are true of the family, such as a size chart. Some are true of the product, such as a detail shot of the fabric. Most are true of the variant, because the blue one and the red one look different. A few are true of a combination that is not a variant axis, such as a lifestyle shot showing three colours together.

    The model that works is an association with a role, held on the product side: this asset, in this role, for this product or variant. Roles are a controlled list. Primary, alternate, detail, lifestyle, size chart, packaging. The channel mapping then says “the marketplace wants the primary plus up to six alternates”, and that is a query rather than a folder convention.

    What the model should not do is put the association in the asset system, for the reasons in DAM vs PIM, and it should not store crops per variant, because renditions are derived rather than stored.
    Macro of a fanned colour swatch deck under raking teal light with two identical amber blades sitting side by side

    When is flattening variants actually correct?

    Twice, and it is worth naming them because the general advice above is otherwise absolute.

    When variants are genuinely different products. If the blue one and the red one have different specifications, different regulatory status, different suppliers and different marketing, they are two products that happen to look similar. Forcing them into a variant grid produces a parent record with almost nothing on it.

    When your only channel demands it. Some marketplaces model everything as a flat list of sellable items with no parent concept. That is a channel mapping problem, not a modelling problem, and the correct response is to keep the structured model and flatten at export. The exception is if you have exactly one channel, forever, and no site of your own, in which case matching its model is defensible and you should write down that you did it on purpose.

    Everything else that looks like a reason to flatten is usually a tool that cannot express hierarchy, which is a reason to check the tool. The questions to ask about that are in what to demand from a PIM API before you buy, and the export-side consequences are in syndicating product data to marketplaces.

    The wider set of modelling decisions this one sits inside is in the product data model that survives growth, and if you are still working out whether a dedicated system is warranted at all, start with what a PIM actually does.
  • The product data model that survives growth

    The product data model that survives growth

    Ask anyone who has replatformed a catalogue what went wrong and you will not hear about the platform. You will hear that the colour attribute was free text, that variants were modelled as separate products, that dimensions were stored as a string with the unit in it, and that by the end nobody could write a query that returned a reliable answer.

    None of those are platform problems. They are modelling decisions, made early, cheaply, by someone under time pressure.

    Short answer: four decisions determine whether a product model survives. Whether attributes are typed, how variants relate to their parent, which fields are localisable, and whether the model is enforced or merely documented. Everything else can be changed later. These four get baked into every downstream integration within about six months.

    Decision one: type every attribute, including the ones that look like text

    An attribute has a type, a unit where relevant, and a vocabulary where the values are drawn from a set. Free text is a type of last resort, not a default.

    The test is whether you will ever want to filter, convert, validate or compare on the field. If yes, it is not text. If you want a public reference point for what a minimally typed product record looks like, the Product schema and its Offer companion are a reasonable floor rather than a ceiling.

    • Number with a unit. Store weight: 2.4 and weight_unit: kg as separate typed values, never "2.4 kg". The moment a market wants pounds you will thank yourself, and the moment a marketplace requires grams you will not have to write a parser.
    • Enumeration. Colour, material, closure type, certification. Draw from a list. The list can be extended; free text cannot be un-extended.
    • Boolean. dishwasher_safe: true, not a text field containing “yes”, “Yes”, “y” and “safe for dishwasher”.
    • Date. Launch date, discontinuation date, certification expiry. Dates as strings sort alphabetically, which is a bug waiting for a locale change.
    • Reference. A link to another record, whether that is a category, a related product or an asset identifier. Never a copy of the other record’s fields.

    The cost of typing late is not the schema change. It is the cleanup pass over existing values, which is manual, and which nobody will fund.

    Decision two: variants are children, not siblings

    This is the modelling error that causes the most rework, and it is invisible for the first year.

    A t-shirt in six colours and five sizes is one product with thirty variants. It is not thirty products, and it is not one product with a text field containing a size list. The distinction matters because the shared attributes have to live in exactly one place.

    The workable structure has three levels: a family that defines which attributes exist, a product that carries the values shared across all its variants, and a variant that carries only the values that differ. Fabric composition sits on the product. Size and colour sit on the variant. Price may sit on either, depending on your business, and if you cannot say which, that is worth resolving before you build anything.

    Model variants as separate products and every shared attribute gets copied thirty times, which means it gets updated in twenty-nine places and missed in one. Attributes, variants and the SKU problem goes through the combinatorics and the two cases where flattening genuinely is correct.

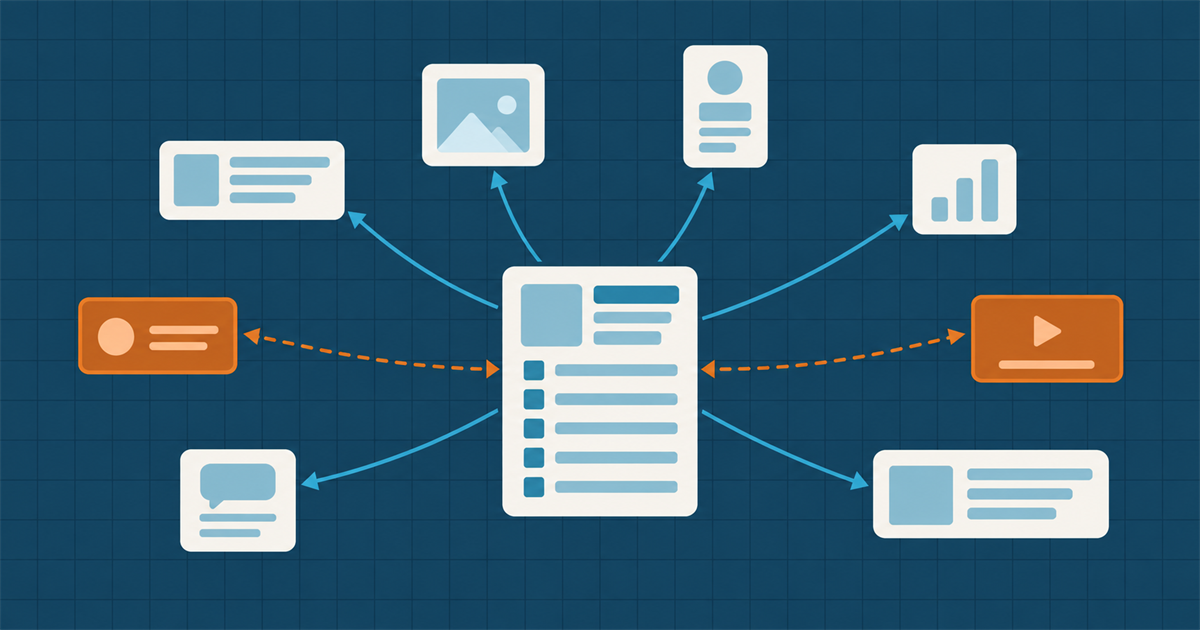
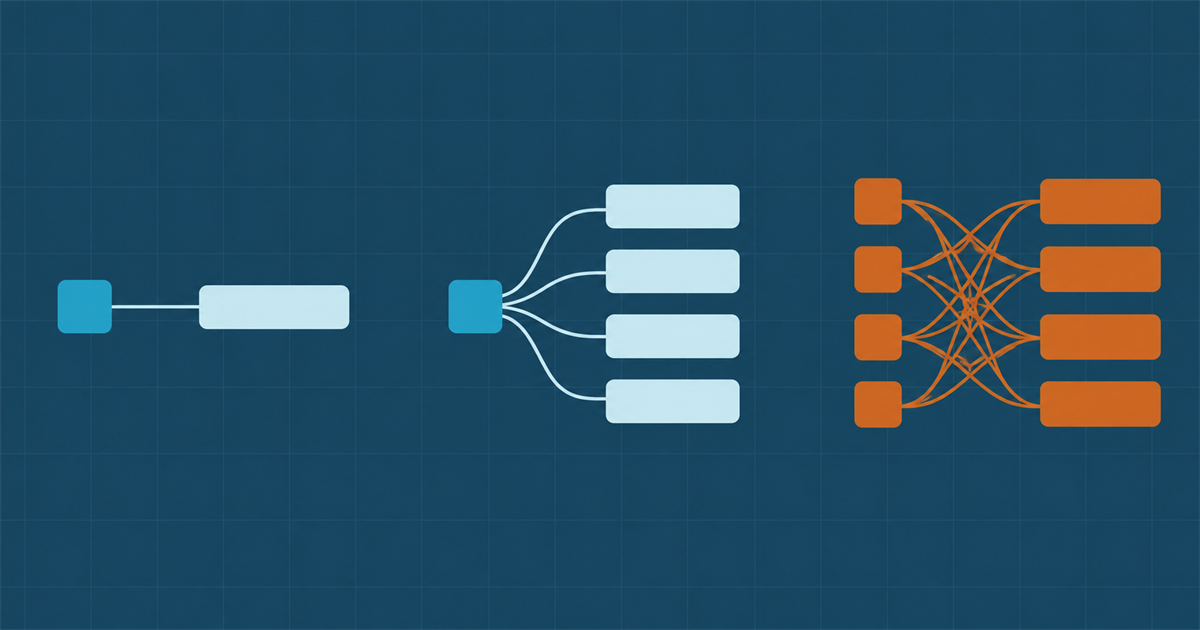
    Three relationship motifs in a row, one-to-one and one-to-many drawn cleanly in teal, many-to-many drawn in amber as a tangled knot

    Decision three: decide what is localisable, and be stingy

    Every attribute is either global or per-market. Choosing badly in either direction hurts.

    Mark everything localisable and you multiply your empty cells by the number of markets, and your completeness reporting becomes noise. Mark nothing localisable and you will be doing a schema migration during a market launch, which is the worst possible time.

    The rule that holds up: an attribute is localisable if its value legitimately differs by market, not if its presentation does. Net weight is global; the fact that one market displays it in pounds is a presentation concern and belongs in the channel mapping, not in the data. Colour is global; the colour name is localisable, because “taupe” is not a word in every market. Marketing copy is localisable by definition. Regulatory fields are localisable and are usually forgotten until the first compliance review.

    A useful discipline is to keep a fourth category: attributes that are global today but have a plausible market-specific future. Do not localise them, but do note them, so that the eventual change is a decision rather than a discovery.

    Decision four: enforce it, or accept that it is fiction

    A schema that is documented but not enforced describes what people intended, not what is in the database. After a year those two things have very little in common.

    Enforcement means the system rejects a value that is not in the vocabulary, refuses to save a required field as empty, and blocks publication to a channel whose rules are not met. It has to happen at write time. Validation reports that run nightly are a way of measuring how bad it got, not of preventing it.

    This is also the honest argument for a dedicated system over a spreadsheet, and it is a narrower argument than the category marketing makes. A spreadsheet can hold a good model. It cannot enforce one. If your model is enforced by convention and a shared understanding among three people, it will survive exactly as long as those three people do.

    Macro of index card edges in a drawer, punched notches aligned into a continuous groove, six cards in the middle notched wrong and lit amber

    Taxonomy, which is a separate thing from attributes

    Categories answer “where does this sit in a browsable hierarchy”. Attributes answer “what is true about this”. Teams routinely encode attributes into the category tree and end up with branches like Furniture > Chairs > Blue Chairs > Blue Oak Chairs, which cannot be maintained and cannot be filtered.

    Keep the taxonomy) shallow and about kind, not about properties. Four levels is usually plenty. Everything that feels like it needs a fifth level is an attribute wearing a category costume, and it should be filterable rather than navigable.

    Expect to maintain more than one taxonomy, because your browse structure and a marketplace’s required category codes will never be the same tree. The mapping problem is old enough to have its own standards work, and the GS1 global data synchronisation network exists largely because two trading partners never agree on one tree. Map between them explicitly rather than trying to satisfy both with one hierarchy.

    What should you model before choosing a platform?

    All four decisions above, on paper, against a real sample of your catalogue. Pick the twenty products that are most awkward, not the twenty that are easiest, and write out their full records by hand. The awkward ones are where the model breaks, and finding that in a document costs an afternoon rather than a quarter.

    Then check the platform against your model rather than the other way round. A tool that cannot express your variant structure will make you flatten it, and the flattening will be permanent. The API-level questions to ask are in what to demand from a PIM API before you buy.

    The model also has to agree with whatever holds your images, because the association between the two is itself a modelled relationship. That boundary is set out in DAM vs PIM, and the discipline that keeps it stable is in single source of truth applied to product data. If you are still deciding whether you need a dedicated system at all, what a PIM actually does is the honest version of the pitch.

  • What a PIM actually does

    What a PIM actually does

    The demo always shows the same thing: a clean grid of products, a completeness percentage climbing toward one hundred, and a button that pushes everything to six marketplaces. It is an accurate demo. It is also the last five per cent of the work, and it hides what the system is actually for.

    Short answer: a PIM holds one authoritative record per product, made of typed and validated attributes, and knows what each destination channel requires from that record. Its real job is refusing to publish incomplete data and telling you exactly which field is missing for which market. Everything else the category sells you is secondary to that.

    The problem it exists to solve

    You sell one product. A marketplace wants a title under eighty characters, five bullet points, a GTIN, a specific category code from its own taxonomy, and a square image on white. Your own storefront wants a longer title, a paragraph of prose, and a lifestyle image. A retail partner wants dimensions in millimetres and net weight in grams. A comparison engine wants a price, a stock state and a shipping class.

    That is one product and four incompatible shapes. The version of this problem everyone starts with is a spreadsheet per channel, which works until a specification changes and only three of the four spreadsheets get updated.

    Product information management is the category name for storing the union of those requirements once, in typed fields, and generating each channel’s shape on demand. The value is not the storage. It is that the union is stated somewhere a machine can check.

    What is actually inside the record

    Four layers, and they are worth separating because teams tend to collapse them and then cannot explain why the model will not scale.

    Identifiers. The SKU you control, plus the external identifiers you do not: GTIN, EAN, MPN. GS1 maintains the identifier standards and marketplaces increasingly reject listings without a valid one, so this layer is not optional even for small catalogues.

    Attributes. Typed values with units and controlled vocabularies. Not “colour: navy blue-ish” but a colour attribute drawn from a fixed list. The typing is the point: an attribute with a type can be validated, converted between units, and filtered on. An attribute stored as free text can only be searched.

    Structure. Which products are variants of which, which belong to which category, and how they group into families. Attributes, variants and the SKU problem covers this layer in detail, because it is where most models break.

    Channel context. Per-channel, per-market overrides and completeness rules. This is the layer that makes a PIM different from a database with a nice interface.

    A specification card with a ruled grid of empty label and value cells, a third filled solid teal, four cells carrying an amber corner fold

    Completeness is the feature

    If you take one idea from this page, take this one. A PIM’s core loop is:

    1. A channel declares its requirements as a rule set. Title length, required attributes, allowed category codes, image count and aspect ratio.
    2. Every product is continuously scored against every rule set it is meant to satisfy.
    3. Publishing is blocked, per channel, until the score is complete.

    That inverts the usual failure. Without it, incomplete data reaches the channel, gets rejected asynchronously, and someone finds out three days later from a report nobody reads. With it, the gap is visible before anything is sent, and it is attributable to a person and a field.

    Google’s product data specification is a good public example of what one such rule set looks like, and the Product schema is a reasonable minimum shape to model against if you are starting from nothing.

    Localisation, which is the part that gets underestimated

    A second market is not a translation job. It is a second set of values for a subset of your attributes, with different units, different regulatory fields, different category placement, and prose that has to be written rather than converted.

    The modelling decision is which attributes are localisable and which are global. Net weight is global. Marketing copy is localisable. Colour name is localisable even though the colour itself is global, which is the sort of distinction that looks pedantic in a workshop and saves a migration later.

    Get this wrong in the direction of “everything is localisable” and you have multiplied your empty fields by the number of markets. Get it wrong the other way and you will be doing a schema change in the middle of a launch.

    A fanned stack of eight identical thin plates, each with the same slot pattern, five filled teal, two partially pale, one with an empty amber slot

    What a PIM does not do

    The category has expanded to the point where vendors claim most of the adjacent surface, so it is worth being blunt about the edges.

    • It is not a DAM. It stores references to assets, not the assets themselves, and its search and rights handling are not built for a media library. The division is set out in DAM vs PIM.
    • It is not an ERP. Stock levels, cost prices, purchase orders and supplier terms belong upstream in the enterprise resource planning system. A PIM reads them at most.
    • It is not a CMS. It does not own page layout, navigation, or editorial content that is not about a product.
    • It is not a storefront. It publishes to one. Treating it as the customer-facing database usually produces a slow storefront and a PIM under read load it was never sized for.

    When is a spreadsheet still the right answer?

    More often than the vendors suggest, and the honest thresholds are these.

    A spreadsheet holds up while all of the following are true: one market, one or two channels, under a few hundred products, attributes that rarely change shape, and one person who owns the file. Under those conditions a PIM adds process without removing work.

    It stops holding up at the first of these: a second market with its own units and copy, a third channel with its own required fields, more than one person editing at once, or a variant structure deep enough that a row can no longer represent a product. That last one is the most common trigger and the least anticipated.

    Do you need a PIM yet works through the arithmetic, including the case for staying on the spreadsheet for another year. Whatever you choose, model the data properly before you choose the tool, because the product data model outlives every platform it has ever been stored in.